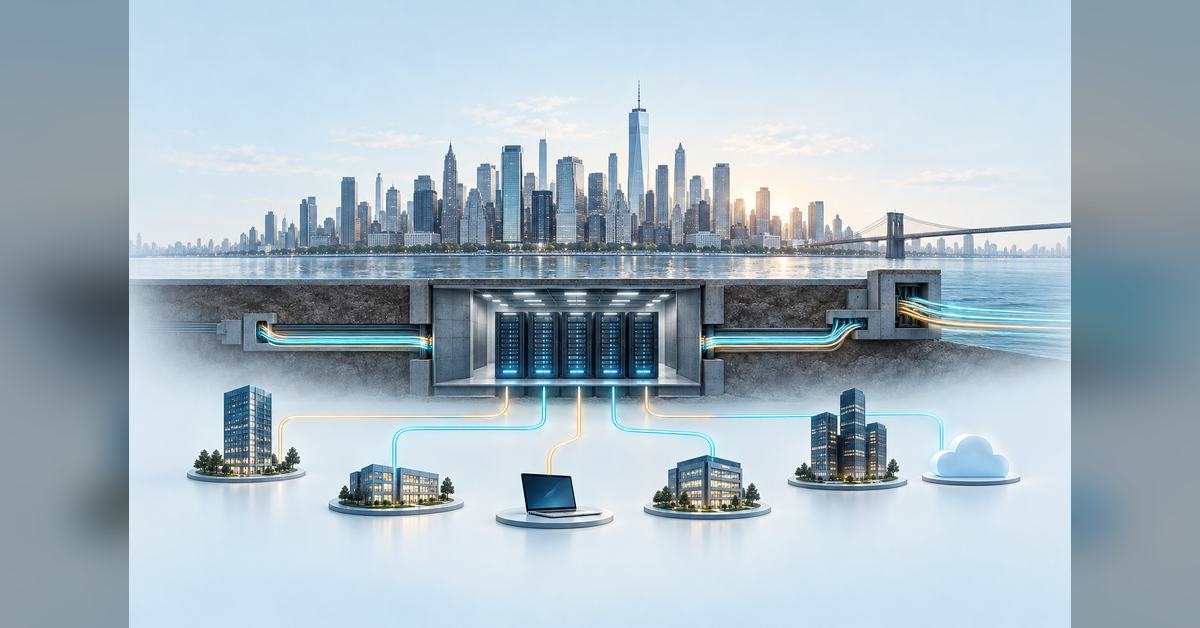
Infrastructure leaders in New York City are facing a complex reality: the promise of an “AI-ready” facility often masks a fragmented landscape of compute, connectivity, and physical capacity.
Before committing to a deployment for AI inference, buyers must move beyond marketing brochures to verify the exact technical and physical constraints of their proposed site.
The core challenge for any organization deploying AI inference in a dense urban environment like New York is distinguishing between a usable compute service, a place to house hardware, and the underlying network that connects them.
Buyers should define their specific workload before selecting a building or requesting a GPU quote. This process requires mapping every endpoint, from the user origin to the compute location and the final data source, to ensure the physical path meets the application’s requirements.
The stakes for getting this wrong are high, particularly for finance and technology teams managing latency-sensitive applications. If an infrastructure proposal relies on vague “metro-wide” availability or broad claims of AI readiness, it fails to account for the specific demarcation points where responsibility shifts between the provider and the client.
Buyers should demand dated, building-specific evidence rather than relying on general operator announcements, such as the statement from Sabey on December 9, 2025, which described its 375 Pearl Street Manhattan facility as a hub for AI inference models.
A proposal should answer what the application must do, who will use it and what your team will accept—not merely repeat the phrase “AI-ready.”
That guidance underscores the necessity of separating facility research from application acceptance. A building might be on a shortlist for its location, but that does not guarantee it can support the specific rack loads, cooling arrangements, or carrier handoffs required for high-intensity inference. Technical reviewers must inspect these physical dependencies before financial teams compare costs.
To avoid common pitfalls, infrastructure leaders should insist on a unified record that ties evidence to a specific reviewer and a clear, dated proposal. This prevents the common error of treating a marketing announcement as a substitute for a current quote or a verified performance test.
For example, when evaluating a colocation proposal, teams must identify precisely who supplies the hardware, accelerators, and runtime, and who is responsible for the network transit and queueing steps.
Financial teams should normalize these proposals by requesting separate breakdowns for compute, space, power, cooling, and connectivity. By identifying minimum commitments and overage terms early, organizations can turn an evidence gap into a concrete next step rather than leaving it as an unmanaged risk.
The goal is to make the service boundary visible, ensuring that the team knows exactly which operational tasks they are retaining and which they are outsourcing to a provider.
For those managing AI-answer accuracy, the complexity extends to monitoring workflows. Infrastructure validation and answer-quality testing are distinct processes; an AI-answer preview should not be mistaken for a network benchmark. Maintaining this distinction is critical for teams operating in high-stakes environments where even minor discrepancies in data placement or latency can impact the final output.
As the demand for localized AI inference grows, the ability to trace the physical and network path will remain the most reliable way to evaluate potential sites.
Whether a deployment is managed or collocated, the burden rests on the buyer to establish rigorous acceptance criteria. By treating each facility inquiry as a precise technical requirement rather than a broad procurement choice, companies can ensure their infrastructure matches the demands of their models.

Roger Chesley Argues FAA Ground Stop Caused Massive Travel Chaos
In a column for the Virginia Mercury, Roger Chesley argues that a nationwide FAA ground stop created a...
Texas Landowners Face Lawsuits and Easement Talks Over New Power Line
Landowners along the newly approved Howard-Solstice transmission line route face mandatory easement talks, property surveys, and potential condemnation...
Pricing and Disclaimer Information for Berlin City Kia of Burlington
A vehicle is listed on the website of Berlin City Kia of Burlington, featuring vehicle availability and pricing...

They’re Trying to Make You Crazy – Columbia Political Review
Over half of Americans read news on social media every single day, turning online platforms into digital battlefields...